Modern AI applications need a reliable platform to train, deploy and run machine learning models at scale. Without the right foundation, teams struggle with slow deployments, costly GPU usage and models that are hard to manage in production.
At OpsBee, our AI Platform Engineering services give your data science and engineering teams a ready-to-use, Kubernetes-native platform for the complete machine learning lifecycle. We bring together MLOps automation, GPU optimization, model monitoring and LLM infrastructure so you can move AI from experiment to production faster across AWS, Azure and Google Cloud.
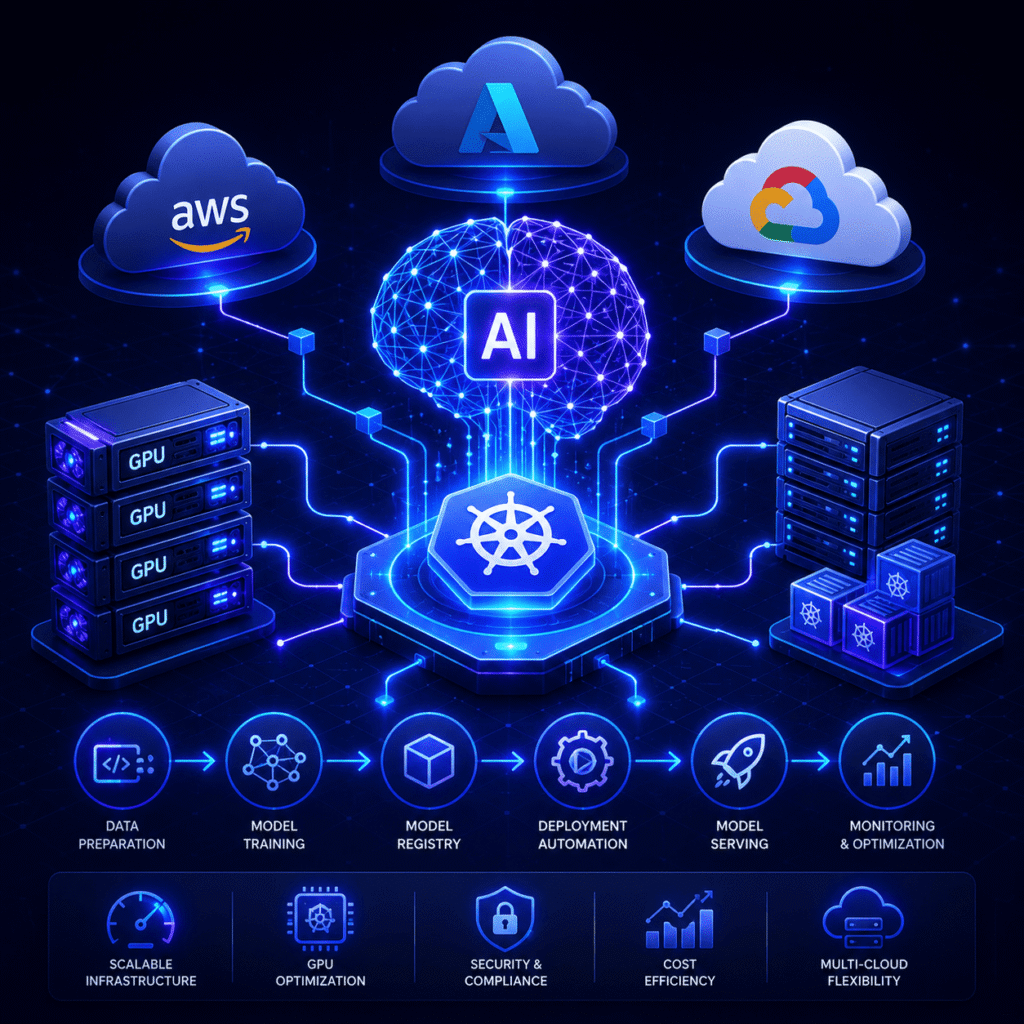
Partner with OpsBee to build an intelligent, automated and scalable AI platform that supports every stage of machine learning, from development to production.
Automate model training, validation, deployment and monitoring using Kubeflow, MLflow, Apache Airflow and cloud-native orchestration tools.
Deploy AI and machine learning models on Kubernetes-based serving platforms with autoscaling, load balancing, canary releases and high-availability inference.
Get more from every GPU with Kubernetes GPU orchestration, NVIDIA GPU Operator integration, intelligent autoscaling and cost-efficient cloud resource management.
Track model performance, detect prediction drift, monitor inference metrics and trigger automated retraining using modern observability tools.
Deploy and manage large language models (LLMs), vector databases, Retrieval-Augmented Generation (RAG) pipelines and generative AI applications on scalable infrastructure.
At OpsBee, we combine cloud engineering, Kubernetes expertise and MLOps automation to help organizations deploy, manage and scale AI workloads with confidence. Our platform-first approach means faster model delivery, better GPU usage, stronger security and stable production operations.
Our AI Platform Engineering Services Help Organizations:
Accelerate model deployment with automated MLOps pipelines for training, testing, release and monitoring.
Reduce AI infrastructure costs by optimizing GPU usage with Kubernetes-powered scaling.
Improve model reliability through continuous monitoring, drift detection and performance tuning.
Build secure, scalable AI platforms across AWS, Azure and Google Cloud.
Simplify day-to-day AI operations with automation, observability and Kubernetes orchestration.
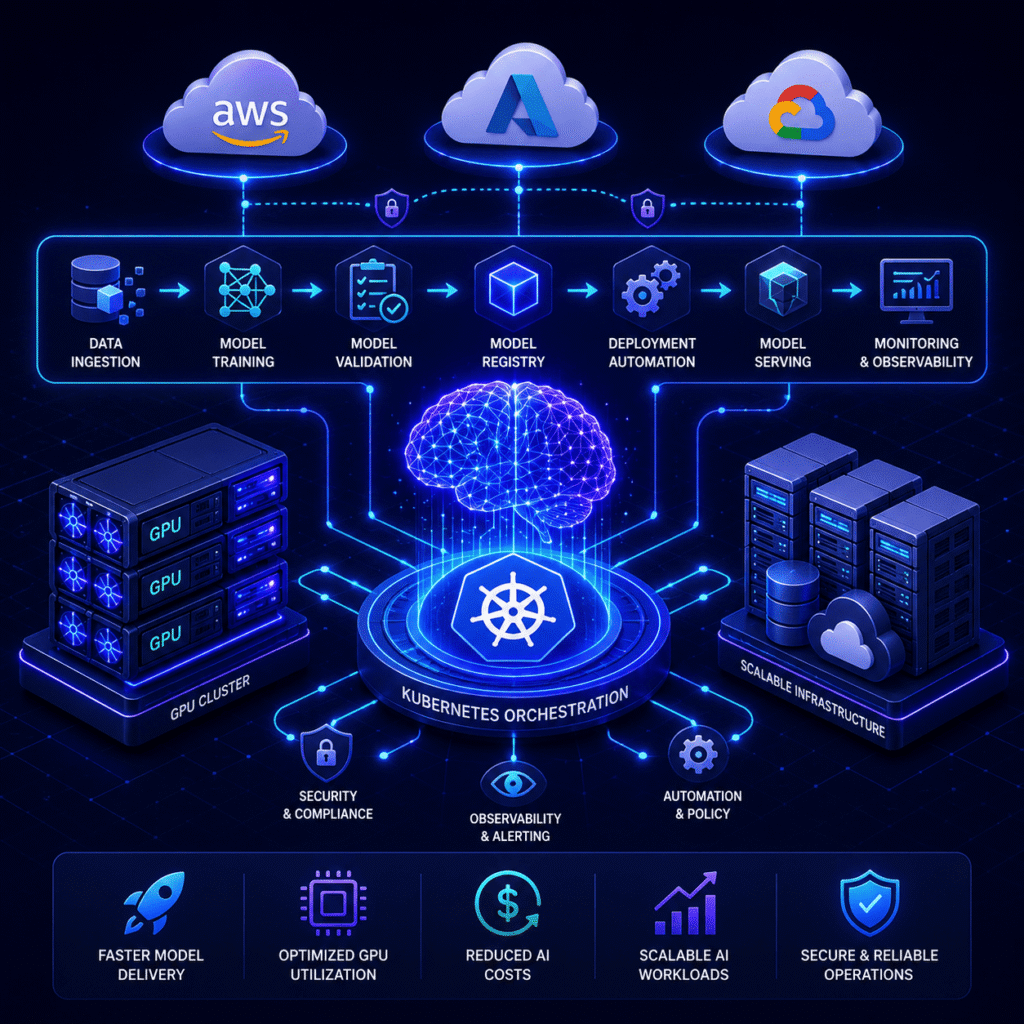
Running AI in production takes more than deploying a model. We follow a clear four-step approach so your platform stays scalable, cost-efficient and easy to manage as your AI work grows.
Automate model training, validation, deployment and retraining to speed up AI delivery and reduce manual work.
Use Kubernetes-based GPU scheduling, autoscaling and smart resource allocation to maximize performance while controlling cloud costs.
Continuously monitor model accuracy, detect drift early and automate retraining to keep predictions reliable.
Run LLMs, vector databases and RAG architectures on production-ready infrastructure built for scale.
Need a strong Kubernetes foundation for your AI workloads? Explore our Kubernetes Platform Engineering services.
Partner with OpsBee for AI Platform Engineering on AWS, Azure and Google Cloud. We help you build, deploy and manage machine learning pipelines with automation, scalability and reliability, so your team can focus on building better models.
Have questions about MLOps, GPU orchestration, LLM deployment or scalable AI infrastructure? Here are the most common questions businesses ask before building their AI platform with OpsBee.
AI Platform Engineering is the design, setup and management of the infrastructure and tools teams use to train, deploy and run AI and machine learning models in production, usually built on Kubernetes and cloud platforms.
MLOps is the set of practices for automating the machine learning lifecycle. AI Platform Engineering builds and runs the platform where those MLOps workflows, GPU workloads and models live.
Kubernetes enables scalable AI workload orchestration, automated deployment, GPU resource management and high availability for machine learning applications.
We use Kubernetes autoscaling, spot instances, GPU scheduling and smart resource allocation to increase GPU utilization and lower cloud compute spend.
Yes. We deploy scalable LLM infrastructure, vector databases, RAG pipelines and high-performance inference systems for enterprise AI applications.
We support AWS, Microsoft Azure, Google Cloud Platform (GCP), hybrid cloud and multi-cloud environments.
OpsBee Technology stands as a trusted provider of IT Managed Services and Infrastructure Solutions, delivering reliable technology support and services across India.
Copyright © 2026 All Rights Reserved.